Most business chatbots give wrong answers for one simple reason: the AI was trained on the internet in general, not on your company’s actual data. Ask it about your return policy, your pricing tiers, or last month’s internal report, and it either makes something up or says it doesn’t know.
Retrieval-Augmented Generation — RAG — exists to fix exactly this problem. It’s one of the most practical AI techniques available to businesses right now, and it’s quietly becoming the backbone of serious AI chatbots, internal knowledge tools, and document-search assistants.
What Is RAG, in Plain Terms
A large language model (LLM) like GPT or Gemini is trained once, on a fixed snapshot of data, and then frozen. It doesn’t know about documents created after its training cutoff, and it has never seen your company’s internal files, product catalog, or support history — because that data was never public in the first place.
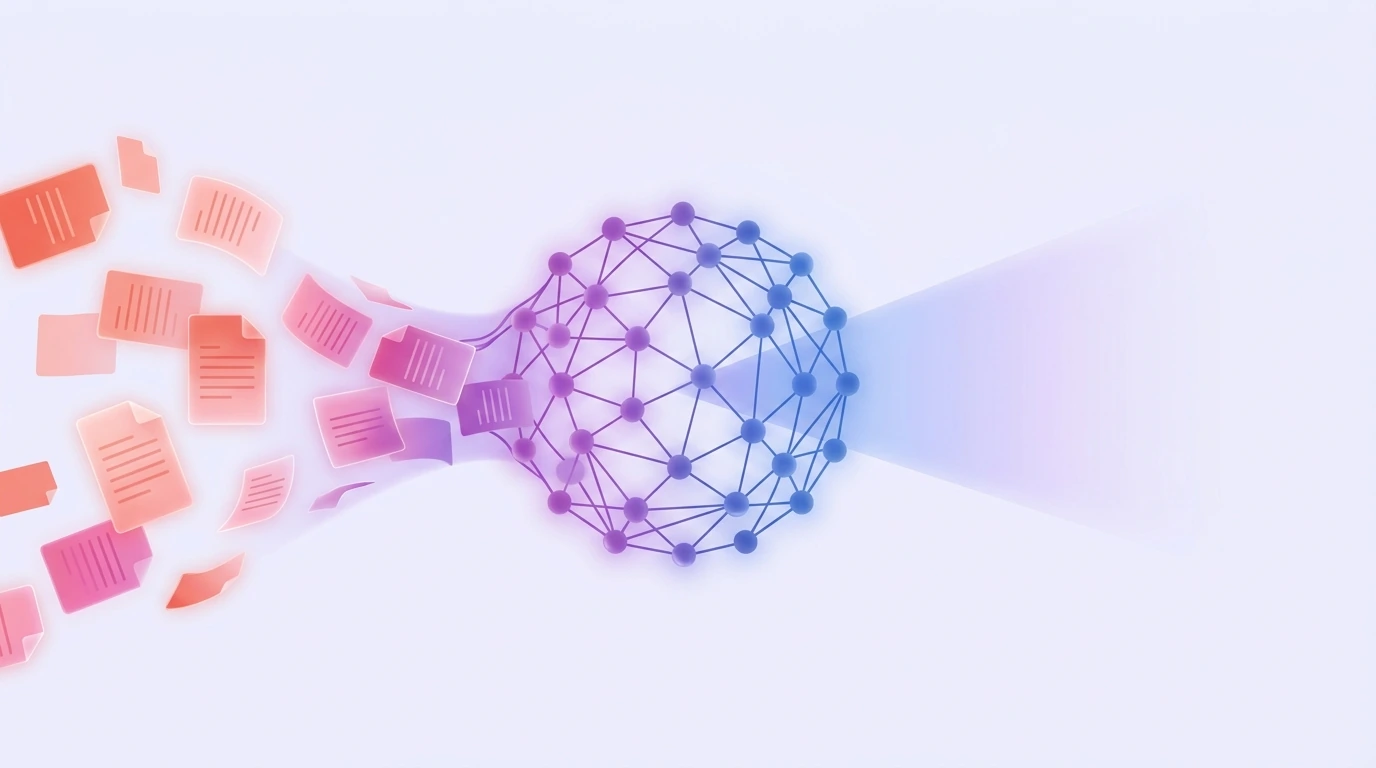
RAG solves this without retraining the model. Instead, it adds a retrieval step in front of the AI:
- A user asks a question.
- The system searches a knowledge base of your real documents — PDFs, wikis, product pages, past support tickets, policy documents — and pulls out the most relevant pieces.
- Those real excerpts are handed to the LLM along with the question, as context.
- The LLM writes its answer using that context, instead of guessing from memory.
The result is an AI that answers using your actual, current information — and can cite exactly where it got the answer from.
Why This Matters More Than It Sounds
Three concrete problems RAG solves for a business:
- It stops the AI from making things up. When an LLM doesn’t know something, it often generates a confident, plausible-sounding wrong answer — a hallucination. RAG gives the model real source material to work from instead of forcing it to guess, which sharply cuts down on fabricated answers.
- It stays current without retraining. Retraining or fine-tuning a model every time a policy, price, or product changes is slow and expensive. With RAG, you just update the documents in the knowledge base — the next query automatically uses the new information. No model retraining required.
- It works with information that was never public. Your internal wikis, contracts, product specs, and support history were never part of any LLM’s training data, and never will be unless you deliberately connect them. RAG is how an AI assistant gets access to that private knowledge securely, without exposing it to the wider internet.
Where Businesses Actually Use RAG
A few common, practical applications:
- Customer support assistants that answer from your real product docs, FAQs, and policies — not generic internet knowledge — and can say “I’m not sure” instead of inventing an answer when nothing relevant is found.
- Internal knowledge search for teams, so employees can ask plain-language questions and get answers pulled directly from company wikis, SOPs, and past documentation instead of digging through folders.
- Document and report analysis, where a system reads through contracts, invoices, or lab reports and answers specific questions about their contents.
- Sales and onboarding tools that answer prospect or new-hire questions using the company’s actual pricing, process, and policy documents.
Does Every Business Need RAG?
Not every chatbot needs it. A simple FAQ bot answering five fixed questions doesn’t need a retrieval pipeline. RAG earns its place when:
- Your knowledge base is large, detailed, or changes often
- Wrong answers carry real cost (support errors, compliance risk, lost trust)
- You need the AI working from information that was never on the public internet
If any of that sounds like your situation, RAG is usually the right foundation — not a nice-to-have add-on.
How It’s Actually Built
A typical RAG system has a few core pieces working together: your documents are broken into chunks and converted into vector embeddings (a numerical representation of meaning, not just keywords), stored in a vector database for fast semantic search (tools like FAISS or pgvector are common choices), and connected to an LLM API that generates the final answer once relevant chunks are retrieved.
Getting the chunking, retrieval accuracy, and prompt design right is where the real engineering work happens — a RAG system built carelessly can still retrieve the wrong context and produce a confident wrong answer, so the implementation details matter as much as the concept.
Frequently Asked Questions
Is RAG the same as fine-tuning a model?
No. Fine-tuning changes the model’s internal weights through additional training, which is slower and more expensive to update. RAG keeps the model unchanged and instead feeds it relevant information at the moment of the query, which makes updates as simple as editing a document.
Does RAG completely stop AI hallucinations?
It significantly reduces them by grounding answers in real retrieved text, but it doesn’t guarantee zero mistakes — the retrieval step and prompt design both need to be built carefully for RAG to be reliable in practice.
Can RAG work with Hindi, English, and mixed-language (Hinglish) content?
Yes — with the right embedding model and retrieval setup, a RAG system can search and respond across multiple languages, which matters for businesses serving Indian users who mix English and Hindi naturally.
What kind of documents can a RAG system use?
PDFs, Word documents, web pages, spreadsheets, support tickets, wikis, and scanned documents (via OCR) can all be processed into a RAG knowledge base, as long as they’re converted into searchable text first.